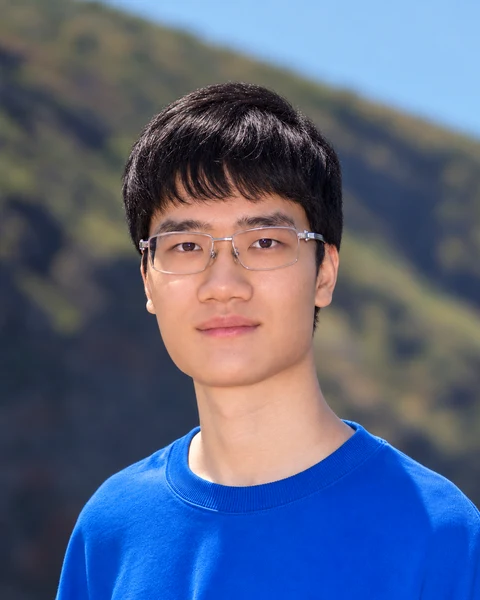
Tiantong Lu

Tiantong Lu (Nathan)

Data Science senior at UC Berkeleyhe/him

Computer Science minor · Data Science Honors Program (in progress)

My current focus is AI for Health: cardiac-risk prediction and the clinical data needed to evaluate it reliably.

My ongoing work also includes low-resource cuneiform recognition and tablet transcription, alongside software development for DNA sequencing.

Tiantong Lu

Research

ECG models for cardiac-risk prediction

Student ResearcherZiad Obermeyer Lab · UC Berkeley School of Public Health

September 2026 – Present

In Professor Ziad Obermeyer’s lab, I fine-tune ECG waveform models, train logistic-regression baselines on clinical features and design feature-ablation experiments for cardiac-risk prediction.

I completed inference on 800,035 MIMIC-IV ECG records on Savio and built workflows linking model outputs to echocardiography and longitudinal hospital data. Model comparisons and outcome-definition analyses are ongoing.

  • ECG waveform fine-tuning
  • Logistic regression
  • Feature ablation
Cohorts, models & outcome definitions

Model comparisons

I compare ECG waveform models with logistic-regression baselines trained on clinical features. Feature-ablation experiments test how input choices affect the comparison. Whether the two sources provide complementary information remains an open research question.

Clinical data engineering

The inference count refers to ECG records, not unique patients or the final linked cohort. My linkage and cohort workflows connect model predictions with echocardiography and subsequent hospital observations for retrospective evaluation.

Outcome definitions and phenotyping

The outcome analyses include one-year ventricular tachycardia/fibrillation and newly documented ejection fraction of 35% or less over 1–12 months. Prior ventricular dysfunction, incomplete follow-up and death as a competing risk affect how these endpoints can be interpreted.

I also develop local LLM-assisted phenotyping of discharge summaries to distinguish sustained VT/VF from nonsustained or historical diagnoses.

Current focus

I am testing how clinical-feature choices and phenotype definitions affect cardiac-risk discrimination in retrospective evaluation.

Mentors: Professor Ziad Obermeyer and Aamir Javaid, MD.

Cuneiform recognition and transcription

Machine Learning & Computer Vision ResearcherTokenWorks LLC · UC Berkeley Data Discovery

June 2026 – Present

I lead research implementation for From Signs to Sequences. I built 387,315 synthetic image–sequence pairs from sign crops and corpus text, and designed token-matched experiments to test how training-data composition affects recognition.

With 100 adaptation tablets, compositional pretraining reduced reconstructed-line sign error by 24–52 percentage points versus omitting that stage, across three recognizers and three evaluation domains. The experiments use known sign locations and a fixed vocabulary.

  • Synthetic training data
  • PyTorch
  • CTC recognition
Experimental controls & results

Compositional training data

Labeled tablet images are limited and vary across historical periods and collections. I compose sign crops into line images using corpus text as the target sequence, creating a deduplicated training pool. Evaluation-tablet texts are excluded from synthetic pretraining.

Token-matched controls

Within one CTC recognizer, I designed token-matched single-sign, shuffled-line and attested-line comparisons. Holding the token budget fixed tests training format beyond supervision quantity. Shuffling changes both order and co-occurrence, so these diagnostic comparisons do not isolate a causal contribution from word order alone.

Results and evaluation scope

The reported reduction compares models with and without the compositional synthetic-pretraining stage, followed by adaptation on 100 real tablets. For example, cross-period SVTRv2* sign error fell from 90.8% to 38.4% (three-seed means). Sign error rate counts insertions, deletions and substitutions relative to the reference sign sequence; lower is better.

This measures recognition of reconstructed lines with known sign locations and a fixed vocabulary, not end-to-end tablet transcription. The separate token-matched controls investigate why training formats differ; they do not causally decompose the full pretraining gain.

From recognition to a transcription system

I also develop a modular tablet-transcription pipeline connecting sign detection, visual recognition, language decoding and sequence verification. Separating the stages makes their individual errors and contributions easier to investigate.

For TabletVLM, I contributed synthetic-line supervision and comparative model evaluation to the team’s end-to-end tablet-transcription study.

Research with Dr. Adam Anderson.

Sanger sequencing software and methods

Student-led research engineeringUC Berkeley DNA Sequencing Facility

September 2026 – Present

I am developing an alternative to the facility’s PeakTrace workflow under Dr. Scott Geller’s supervision. I set the technical roadmap, implement the software and design the evaluation.

I built AB1 trace diagnostics and reference-based sequence-scoring tools, and compiled and tested the open-source TraceTuner basecaller. I am designing a matched-input PeakTrace comparison of sequence errors, trimming and reliable read length.

  • Python
  • Signal processing
  • Paired evaluation
Tools & evaluation design

Trace diagnostics and scoring

The Python tools inspect AB1 signal channels, peaks, basecalls and quality scores. Reference-based scoring measures sequence errors, ambiguous bases and called length. These diagnostics help identify where basecalling and trimming choices affect an output sequence.

Matched-input comparison

The planned evaluation will run TraceTuner and PeakTrace on identical AB1 inputs and compare sequence errors, ambiguity, trimming and reliable read length against a reference. Its error analysis will guide subsequent signal-processing or learning-based development.

Supervised by Dr. Scott Geller.

Earlier works

Multilingual book OCR

Research InternTokenWorks LLC

January – June 2026

In a four-person team, I led evaluation of multilingual book-OCR workflows, comparing recognition errors, reading order, diacritics and throughput on noisy scans. I built internal benchmarking tools and used the results to guide preprocessing and text extraction.

Research data pipelines for AI and labor markets

Data Science ResearcherHaas School of Business, UC Berkeley

January – May 2026

I built a PostgreSQL pipeline to collect RentAHuman.ai postings every six hours, with parsing and deduplication for a longitudinal study of AI and online labor markets. I also applied positive-unlabeled learning to analyze posting visibility and task turnover.

Papers & manuscripts

From Signs to SequencesCompositional Synthesis for Cuneiform Recognition Across Periods and Collections

Co-first authorSubmitted to ICLR 2027 · awaiting peer review

Designed the synthetic-data and token-matched CTC experiments; led data construction, model training and evaluation.

TabletVLMEnd-to-End Cuneiform Tablet Transcription with a Spatially Grounded Vision Language Model

Co-first authorSubmitted to ICLR 2027 · awaiting peer review

Contributed synthetic-line supervision and comparative model evaluation to the team’s end-to-end tablet-transcription study.

Beyond String AgreementSource Consensus, Sign Identity, and Provenance in Cuneiform Unicode Conversion

Co-first authorManuscript complete · not submitted

Investigates why Unicode string disagreement can reflect encoding conventions rather than different sign identities. I led evaluation and statistical analysis of six resources across 565,542 reference-encoding tokens, produced the figures and tables, and co-wrote the manuscript.

These manuscripts are not yet publicly posted. Public links will appear here when available.

About

Education

University of California, Berkeley

2025–2027 · expected May 2027

B.A. in Data ScienceComputer Science minorDomain Emphasis: Applied Mathematics and Modeling

Data Science Honors Program, 2026–2027 (in progress)

College of the Canyons

2023–2025

A.S. degrees: Computer Science, Mathematics and PhysicsA.A. degree: EconomicsValedictorian, Class of 2025

Research timeline

  1. September 2026 – PresentECG models for cardiac-risk prediction
  2. September 2026 – PresentSanger sequencing software and methods
  3. June 2026 – PresentCuneiform recognition and transcription
  4. January – June 2026Multilingual book OCR
  5. January – May 2026Research data pipelines for AI and labor markets

Teaching

Math and Science Tutor

June 2024 – June 2025

The Learning Center, College of the Canyons

Provided one-to-one and small-group tutoring in calculus, linear algebra, differential equations, physics and statistics.

Organized exam-review workshops and curated practice questions, using worked examples to help students choose methods, identify mistakes and check their reasoning.

Selected coursework

  • Machine Learning (CS 189, current)
  • Artificial Intelligence (CS 188)
  • Data Engineering (DATA C101 / CS C187, current)
  • Data Mining and Analytics (DATA 144, current)
  • Probability (STAT 134)
  • Optimization (EECS 127)
  • Numerical Analysis (MATH 128A)
  • Internet Architecture and Protocols (CS 168)
  • User Interface Design and Development (CS 160)

Courses marked current are in progress in Fall 2026.

Course project

Pockit

A five-person course prototype for spending, subscriptions and credit-card management. I contributed needfinding interviews and paper-prototype usability testing.

CS160 course-team prototype · Summer 2026

Get in touch

For research opportunities and conversations about my work,
please email me.

Campus photography: Tiantong Lu (Sather Tower) and Josh Kahen / The Daily Californian.